Independent knowledge base software guide Evidence-led Updated 2026


Knowledge Base Maturity Model: 5 Levels, Assessment, and Roadmap
A Knowledge Base Maturity Model is a diagnostic framework for evaluating how consistently an organization creates, governs, maintains, finds, reuses, measures, and improves knowledge. It helps distinguish a trusted knowledge operation from a repository that simply contains a large number of documents.
There is no single universal standard called “the” Knowledge Base Maturity Model. Broader knowledge management frameworks exist, but organizations apply different stages, dimensions, and scoring methods to customer help centers, internal knowledge bases, IT service management, product documentation, and AI knowledge systems.
This article presents a practical, evidence-informed framework for assessing knowledge base operations. It is an assessment and planning tool, not an official certification standard.
Information reviewed on November 13, 2026.
The five knowledge base maturity levels at a glance
The model uses five levels, numbered from 0 to 4. Each level represents a meaningful change in operating capability, not merely the purchase of additional software.
| Level | Maturity stage | Typical reality | Main risk | Next priority |
|---|---|---|---|---|
| 0 | Fragmented | Knowledge is scattered across email, chat, shared drives, individual files, and employee memory. | Users cannot identify the current or authoritative answer. | Define scope, inventory critical knowledge, and assign initial owners. |
| 1 | Centralized | A common repository exists, but content structure, ownership, review, and search remain inconsistent. | The knowledge base becomes a better-organized dumping ground. | Create standards, templates, ownership rules, and a basic lifecycle. |
| 2 | Standardized | Priority content follows repeatable structures, metadata, workflows, and review practices. | Processes exist but are not consistently measured or enforced. | Formalize governance, risk-based review, analytics, and feedback management. |
| 3 | Governed and measured | Ownership, approvals, access, lifecycle controls, and knowledge health metrics are actively managed. | Teams may measure activity without proving that users complete tasks successfully. | Connect knowledge performance to user journeys, workflow outcomes, and business priorities. |
| 4 | Adaptive | Knowledge is continuously improved from search, workflow, feedback, operational, and AI retrieval signals. | Optimization can weaken if governance is sacrificed for speed or automation. | Maintain controls while improving content, delivery, and retrieval as needs change. |
The goal is not automatically to reach Level 4 in every area. A low-risk employee FAQ may not require the same controls as technical troubleshooting, legal guidance, financial procedures, or safety-critical instructions. The appropriate target depends on audience, demand, business value, and the consequences of an incorrect answer.
What a knowledge base maturity model evaluates
A useful maturity model evaluates the operating system behind the content. It asks whether the organization knows which knowledge matters, who owns it, how quality is controlled, how users find it, and how evidence leads to improvement.
It should not treat article volume, platform age, search technology, or chatbot deployment as proof of maturity. An organization can have thousands of articles and still provide conflicting answers. It can also deploy generative AI over content that is outdated, duplicated, poorly permissioned, or missing important context.
Knowledge base maturity versus related frameworks
Knowledge base maturity overlaps with broader knowledge management, content operations, KCS, and AI readiness, but these concepts do not evaluate exactly the same thing.
| Framework or discipline | Primary scope | How it relates to knowledge base maturity |
|---|---|---|
| Knowledge Base Maturity Model | The operational health of one or more knowledge bases | Evaluates content, ownership, lifecycle, findability, user outcomes, measurement, permissions, and improvement. |
| Knowledge Management Maturity Model | The organization’s wider ability to create, transfer, share, retain, and apply knowledge | Includes broader strategy, culture, people, leadership, processes, and technology beyond a specific repository. |
| KCS | Creating, reusing, and improving knowledge while work is performed | Provides practices that can improve contribution, reuse, article quality, coaching, and workflow integration. |
| Content maturity model | Content strategy, operations, governance, design, and delivery | May cover channels and content types beyond knowledge articles and support documentation. |
| Self-service maturity | Whether users can complete intended tasks without assisted support | Represents an important outcome of knowledge maturity but does not fully cover governance or internal operations. |
| AI or RAG readiness | Whether approved content can be retrieved and used reliably by an AI system | Should be assessed as a distinct dimension or overlay, not treated as proof of overall maturity. |
| ISO 30401 | Requirements for a knowledge management system | Provides management-system requirements, not a knowledge base maturity score or certification ladder. |
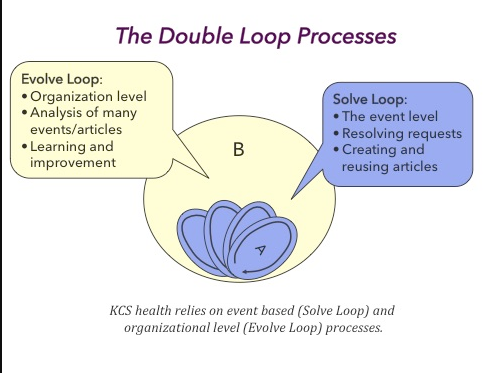
The KCS v6 Practices Guide, for example, focuses on integrating knowledge capture, reuse, and improvement into the workflow. Its article guidance emphasizes simple structure and content that is findable and usable by the intended audience. A maturity assessment can show whether those practices are established, consistently applied, and producing useful outcomes.
ISO 30401:2018 remains the published international standard for knowledge management systems, with amendments, while a proposed second edition, ISO/DIS 30401, remains under development. Neither document should be presented as an official Knowledge Base Maturity Model.
How this framework was developed
This model combines recurring principles from established knowledge management, service knowledge, content governance, and AI-readiness sources without reproducing any proprietary assessment.
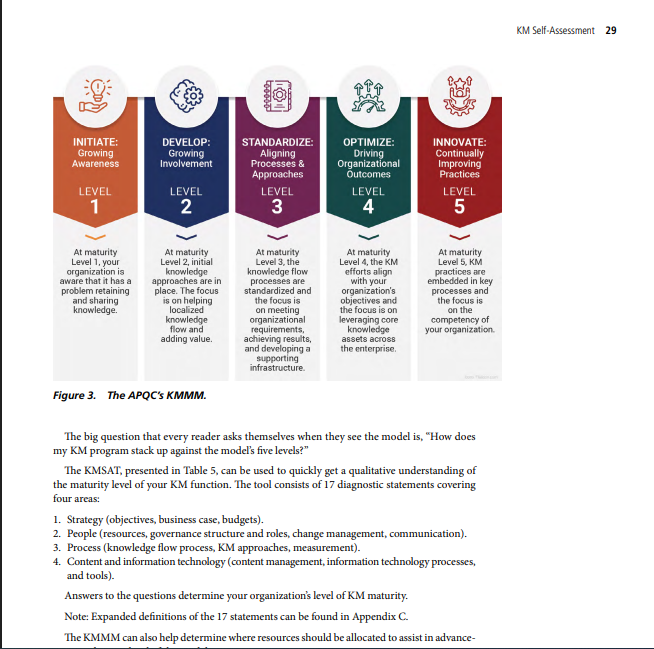
- APQC’s Knowledge Management Capability Assessment Tool evaluates KM through a five-step maturity model and provides separate ratings across multiple component areas rather than relying only on one overall score.
- The academic General Knowledge Management Maturity Model assesses people, process, and technology and describes maturity modeling as a way to understand current status and guide implementation.
- The National Academies’ KM self-assessment guidance evaluates areas including strategy, people, process, content, and information technology.
- The Microsoft 365 community knowledge management scenario considers content, collaboration, and community. It is community-supported, open-source content rather than an official Microsoft standard.
- Salesforce guidance on how to prepare source content for AI emphasizes specific, organized, detailed, accurate, permission-aware, and testable knowledge.
The resulting framework focuses specifically on the capabilities required to operate a trustworthy, findable, measurable, and improvable knowledge base.
Level 0: Fragmented knowledge
At Level 0, knowledge exists, but it is dispersed across personal files, old intranet pages, shared folders, email threads, chat messages, ticket histories, and employee memory. Different teams may maintain separate versions of the same answer.
Users depend on knowing whom to ask or where to look. New employees learn through shadowing, and experienced employees often act as human search engines. When those employees are unavailable, the organization loses access to important context.
Evidence of Level 0
- No agreed repository or authoritative source exists.
- Content ownership is unknown or based on personal knowledge.
- Duplicate and contradictory instructions are common.
- Search behavior and content demand are not measured.
- Important answers frequently move through private conversations.
- Updates depend on individual initiative rather than a defined process.
Primary risk: people cannot reliably identify which answer is current, accurate, or approved.
Next move: define one assessment scope, identify high-demand or high-risk knowledge, inventory the main sources, and assign an accountable owner to each critical area. Do not begin by migrating every available file.
Exit criteria: the organization has selected an authoritative destination for the assessed scope, identified its critical knowledge, and assigned ownership for priority content.
Level 1: Centralized repository
At Level 1, the organization has established a knowledge base or consolidated a meaningful portion of its content. Users have a recognized place to search, but the repository lacks consistent operating rules.
Articles may use different structures, titles, terminology, and levels of detail. Some have owners and review dates, while others were imported without a clear lifecycle. Search performance varies because content was centralized without being sufficiently redesigned.
Evidence of Level 1
- A common repository exists for the defined audience or domain.
- Publishing rights are available but may be loosely controlled.
- Templates are optional, inconsistent, or limited to certain teams.
- Metadata and categories reflect local habits rather than a shared standard.
- Review and retirement occur mainly after a problem is reported.
- Success is measured through article count, page views, or migration progress.
Primary risk: the platform creates the appearance of order while inconsistent and obsolete content continues to reduce trust.
Next move: define article types, minimum quality requirements, ownership fields, approved terminology, review triggers, and a simple information architecture based on user needs rather than the organization chart alone.
Exit criteria: priority content uses documented templates and metadata, has named owners, and follows a repeatable create-review-publish-retire process.
Level 2: Standardized knowledge operations
At Level 2, knowledge practices are documented and repeatable across the assessed scope. Teams use common article structures, metadata rules, publishing workflows, and ownership expectations. Search and content health are no longer treated solely as platform problems.
Knowledge may also begin to move into the workflow. Support agents reuse and improve articles while resolving cases, IT teams connect knowledge to incidents, or product documentation updates are linked to release processes.
Evidence of Level 2
- Defined article templates and content standards are in regular use.
- Owners and review dates are required for priority content.
- A taxonomy or metadata standard supports navigation and filtering.
- Draft, approved, archived, and obsolete states are distinguishable.
- Search queries, failed searches, and user feedback can be reviewed.
- Contributors understand how to propose, create, or improve knowledge.
- Permissions are defined by audience or content sensitivity.
Primary risk: documented processes may exist without consistent enforcement, reliable reporting, or evidence that users complete their intended tasks.
Next move: establish formal governance, risk-based review schedules, content audits, feedback ownership, search improvement routines, and a small set of outcome-oriented measures.
Exit criteria: teams can demonstrate that governance controls are operating, exceptions are visible, and knowledge performance is reviewed through evidence rather than assumptions.
Level 3: Governed and measured knowledge
At Level 3, ownership, quality, lifecycle, access, and measurement are actively managed. Governance is not limited to a policy document; named people review exceptions, prioritize gaps, and make decisions.
High-risk content receives stronger controls than low-risk content. Search failures, unresolved feedback, overdue reviews, and content gaps enter managed backlogs. Teams measure whether knowledge is helping users, not merely whether it is being published.
Evidence of Level 3
- Governance roles and decision rights are documented and used.
- Critical content is identified and subject to appropriate approval and review controls.
- Owners receive reports on overdue, low-quality, or high-risk articles.
- Search and user feedback produce prioritized improvement work.
- Content audits use consistent criteria rather than personal preference.
- Permissions and publishing rights are periodically reviewed.
- Dashboards combine content health, findability, adoption, and user outcome signals.
- Teams can explain why selected metrics matter to the intended business outcome.
Primary risk: the program may optimize dashboards and processes without understanding whether users can complete the task that brought them to the knowledge base.
Next move: connect knowledge data to user journeys, support demand, product changes, training, operational processes, and recurring failure patterns. Use qualitative research alongside analytics.
Exit criteria: improvement priorities are based on combined evidence from content health, search behavior, workflow use, user research, and operational outcomes.
Level 4: Adaptive knowledge operations
At Level 4, knowledge is treated as an operating capability that changes with user demand, products, policies, workflows, and risk. Feedback from human users, search systems, service operations, and AI retrieval is converted into controlled improvement.
Knowledge creation and maintenance are embedded in relevant work. The organization can test whether content supports important tasks, identify gaps before they become widespread, and adjust governance according to risk.
Evidence of Level 4
- Knowledge priorities are tied to strategic, service, product, or operational needs.
- Content gaps and recurring user failures feed product, process, and training improvements.
- Governance controls vary appropriately by risk and audience.
- Article creation, reuse, feedback, and improvement are integrated into relevant workflows.
- Teams regularly test search, self-service, and AI retrieval against realistic questions.
- AI answers can be traced to authorized sources where the use case requires it.
- Incorrect, incomplete, or poorly retrieved answers produce measurable corrective work.
- The organization reassesses its target state as needs and risks change.
Primary risk: pressure to automate or publish faster may weaken source control, review, permissions, or human oversight.
Next move: maintain the operating discipline. Level 4 is not a permanent destination; it requires continuous evidence that knowledge remains useful, trustworthy, accessible, and appropriately controlled.
Nine dimensions to assess
Assess maturity by dimension rather than assigning one score from a general impression. A knowledge base can be strong in technology but weak in ownership, or well governed but difficult for users to search.
| Dimension | Diagnostic question | Evidence to examine |
|---|---|---|
| 1. Strategy and scope | Why does this knowledge base exist, whom does it serve, and which outcomes matter? | Knowledge strategy, audience definition, business objectives, scope statement, priority use cases. |
| 2. Governance and ownership | Who can make decisions, approve content, resolve conflicts, and accept risk? | Governance policy, ownership map, role definitions, decision log, escalation path. |
| 3. Content quality and lifecycle | How does the organization keep important content accurate, current, useful, and appropriately retired? | Content standards, templates, review schedules, audit results, archive log, owner coverage. |
| 4. Structure, metadata, and findability | Can users and systems retrieve the correct answer using the language and context available to them? | Taxonomy, metadata standard, search logs, zero-result queries, synonyms, usability tests. |
| 5. Knowledge capture and workflow | Is knowledge created and improved as part of real work, or only through occasional documentation projects? | Contribution workflow, KCS practices, case or incident links, subject matter expert process, feedback routing. |
| 6. User experience and self-service | Can the intended audience understand the content and complete the intended task? | Task testing, user research, accessibility review, article feedback, escalation after article use. |
| 7. Measurement and improvement | Do metrics reveal problems and lead to decisions? | Knowledge health dashboard, improvement backlog, review meetings, trend reports, action owners. |
| 8. Security, platform, and integration | Can the right audience access current knowledge without exposing restricted information or creating uncontrolled copies? | Permission audit, SSO configuration, publishing rights, source-system map, integration logs, export process. |
| 9. AI and RAG readiness | Can an AI system retrieve approved, current, relevant, and permission-appropriate content and show where it came from? | Source inventory, version metadata, retrieval test set, citation review, security-trimming tests, answer-quality backlog. |
Not every organization needs to assess all nine dimensions at the same depth. An internal HR knowledge base may emphasize permissions and policy versioning, while a public product help center may emphasize findability, task completion, and release alignment.
A practical knowledge base maturity scorecard
Score each relevant dimension from 0 to 4 using observable evidence. Do not choose a score based solely on what a policy says should happen. Score what can be demonstrated across the defined scope.
| Score | Meaning | Evidence standard |
|---|---|---|
| 0 | Not established | No repeatable capability or reliable evidence exists. |
| 1 | Ad hoc or localized | Some individuals or teams perform the activity, but execution is inconsistent and dependent on personal effort. |
| 2 | Defined and repeatable | A documented method is applied to priority content or within the assessed scope, although exceptions remain. |
| 3 | Governed and measured | The capability is consistently managed, exceptions are visible, and evidence is reviewed. |
| 4 | Adaptive and improving | Evidence regularly leads to controlled improvement, and the capability changes as user needs and risks change. |
Scorecard questions
- Strategy and scope: Can stakeholders explain the audience, priority use cases, expected outcomes, and boundaries of the knowledge base?
- Governance and ownership: Does every critical knowledge area have an accountable owner and a functioning decision process?
- Content quality and lifecycle: Can the organization show which critical articles are current, overdue, duplicated, unapproved, or obsolete?
- Structure and findability: Can users find the correct answer using realistic terminology, context, and navigation paths?
- Capture and workflow: Do people create, reuse, and improve knowledge during the work that generates it?
- User experience: Can representative users understand the content and complete the intended task?
- Measurement: Do reports reveal specific problems, owners, priorities, and completed corrective actions?
- Security and integration: Are access, publishing, source ownership, and system connections controlled and periodically tested?
- AI and RAG readiness: Can the organization test retrieval, citations, versions, permissions, and answer quality against realistic questions?
How to interpret the results without false precision
The primary result should be a maturity profile showing the score and evidence for each dimension. A single average can hide the exact problem the assessment is intended to reveal.
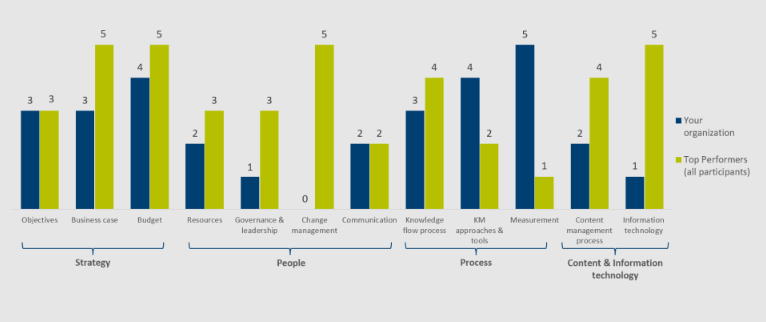
For example, strong technology and search scores should not compensate for unowned content, weak approval controls, or permission failures. Treat content accuracy, lifecycle ownership, and access control as critical gates where the risk of failure is high.
- Use the dimension profile as the main result.
- Use an overall level only as a concise description of the dominant operating pattern.
- Record exceptions and mixed maturity explicitly.
- Assess customer, agent, employee, product, and policy knowledge separately when their operations differ.
- Do not compare teams unless they use the same scope, definitions, and evidence requirements.
- Do not present the result as an industry benchmark unless a credible comparable dataset exists.
- Choose a target level based on value and risk rather than automatically selecting Level 4.
A low score is not a failure. It identifies the dependency that should be addressed before the organization adds more content, tools, channels, or automation.
Hypothetical assessment example
Consider a customer support knowledge base with the following evidence-based scores. This is a hypothetical example intended to demonstrate the method, not a benchmark or real case study.
| Dimension | Score | Observed evidence |
|---|---|---|
| Strategy and scope | 2 | The audience and major use cases are defined, but objectives are not consistently connected to support priorities. |
| Governance and ownership | 1 | Some product teams own content, while many high-use articles have no accountable owner. |
| Content quality and lifecycle | 2 | Templates and reviews exist, but overdue content is not consistently escalated. |
| Structure and findability | 2 | Search analytics are available, although failed searches do not enter a managed backlog. |
| Capture and workflow | 1 | Agents submit occasional requests, but knowledge improvement is separate from case resolution. |
| User experience | 2 | Article ratings are collected, but top self-service journeys have not been tested. |
| Measurement | 1 | The dashboard emphasizes page views and article count. |
| Security and integration | 3 | Roles, publishing rights, SSO, and internal access are actively managed. |
| AI and RAG readiness | 1 | A chatbot is connected, but no repeatable retrieval test set or citation review exists. |
An arithmetic average would place this knowledge base somewhere between Levels 1 and 2, but that summary is less useful than the profile. The main bottlenecks are ownership, workflow integration, measurement, and AI evaluation.
The first priorities should be to assign owners to high-demand content, convert failed searches and unresolved cases into a managed knowledge-gap backlog, and create a realistic retrieval test set before expanding chatbot use.
How to run the maturity assessment
1. Define the scope
Select a specific knowledge domain, audience, product, department, or channel. “All organizational knowledge” is usually too broad for a useful first assessment.
2. Define the outcomes
Agree on the problems the assessment should help solve. Examples include repeated support demand, slow onboarding, inconsistent agent answers, outdated policy content, failed searches, or unreliable AI retrieval.
3. Select participants
Include the knowledge owner, a representative of the intended users, content or documentation staff, the platform or search owner, and relevant operational stakeholders. Add security, compliance, analytics, or AI specialists when the scope requires them.
4. Collect evidence before scoring
Request a manageable evidence set: content inventory, ownership report, review status, search logs, feedback queue, permission model, workflow documentation, and current dashboards. Interviews are valuable, but they should not replace operational evidence.
5. Score dimensions independently
Have participants record a score and the supporting evidence before the calibration discussion. This reduces the tendency to agree with the most senior or confident person in the room.
6. Calibrate disagreements
When scores differ, identify the cause. The participants may be evaluating different departments, channels, or article types. Record mixed maturity instead of forcing a false consensus.
7. Identify bottlenecks and dependencies
A weak capability may block several others. For example, AI testing will not solve conflicting source content, and a new search platform will not fix articles that lack clear titles, audience context, or ownership.
8. Set a realistic target state
Select the level required for the scope rather than setting Level 4 as a universal target. Define the evidence that must exist before the target is considered achieved.
9. Assign actions, owners, and measures
Every priority should have a named owner, completion evidence, and a measure showing whether the change addressed the original problem.
A practical 90-day improvement roadmap
The following roadmap is a planning example, not a universal implementation timeline. Adjust the scope to the size, risk, and available resources of the knowledge base.
Days 1–30: Establish control and evidence
- Define the knowledge domain and intended audience.
- Identify the highest-demand and highest-risk content.
- Map current repositories and authoritative sources.
- Assign owners to critical knowledge areas.
- Collect baseline search, feedback, review, and permission data.
- Document the most important quality and governance gaps.
Days 31–60: Standardize the operating model
- Define article types and minimum content standards.
- Create or revise templates around specific user intents.
- Establish metadata, audience, version, and ownership requirements.
- Create a risk-based review and retirement process.
- Route feedback and failed searches into a managed backlog.
- Clarify publishing rights, approval paths, and escalation rules.
Days 61–90: Test outcomes and improve
- Improve a small group of high-value articles or user journeys.
- Test whether representative users can find and apply the content.
- Review zero-result and low-success searches.
- Build a balanced knowledge health dashboard.
- Document resolved gaps and remaining dependencies.
- For AI use cases, create retrieval questions and verify sources, citations, versions, and permissions.
At the end of the cycle, reassess the affected dimensions. The goal is not to claim that the entire organization has advanced a level; it is to show that specific capabilities now have stronger evidence.
Metrics that indicate real maturity
No single metric proves maturity. Use a balanced set that covers content health, findability, workflow, user outcomes, governance, and improvement.
| Measurement area | Useful signals | Question answered |
|---|---|---|
| Ownership and lifecycle | Owner coverage, overdue review rate, archive rate, critical-content review status | Is important knowledge actively maintained? |
| Content quality | Audit pass rate, duplicate-content findings, unresolved accuracy issues | Can users trust the content? |
| Findability | Search success, zero-result queries, repeated refinements, time to locate an answer | Can users retrieve the right content? |
| User outcomes | Task completion, usability findings, escalation after knowledge use, reason for negative feedback | Does the content help users complete the intended task? |
| Knowledge flow | Article reuse, improvement rate, feedback age, knowledge-gap closure | Is knowledge being captured and improved through work? |
| Governance | Approval cycle time, overdue decisions, access exceptions, permission findings | Are controls operating as intended? |
| AI retrieval | Retrieval test pass rate, source relevance, citation coverage, permission-alignment findings | Can AI retrieve approved and appropriate knowledge? |
Metrics such as ticket deflection, average handle time, productivity, or cost savings may be useful, but they do not automatically prove that knowledge caused the change. Credible causal claims require appropriate baselines, definitions, and analysis.
How to assess AI and RAG readiness
An AI-enabled knowledge base is not necessarily a mature knowledge base. A chatbot can be connected to an ungoverned repository, and a RAG system can retrieve content that is stale, contradictory, unauthorized, or missing important conditions.
Salesforce’s guidance for AI source content emphasizes making knowledge specific, organized, detailed, and accurate. It also recommends clear semantic structure, audience and access metadata, version information, retrieval testing, and ongoing monitoring.
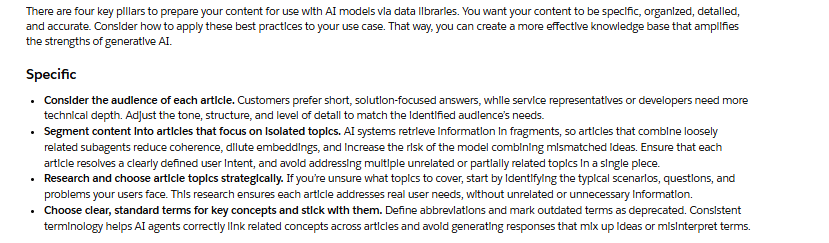
AI-readiness checklist
- Authoritative sources are identified.
- Every high-risk topic has an accountable owner.
- Current and obsolete versions are distinguishable.
- Duplicate and conflicting content is managed.
- Articles address clear user intents rather than unrelated topics.
- Headings and fields create meaningful semantic boundaries.
- Audience, product, version, geography, and access metadata are available where needed.
- Retrieval respects the user’s permissions.
- Answers can show or link to supporting sources when the use case requires it.
- A representative test set covers common, difficult, ambiguous, and high-risk questions.
- Failed or incorrect answers create tracked improvement work.
- High-risk outputs receive appropriate human review.
AI readiness should normally be treated as its own dimension or as an overlay across content, metadata, permissions, and measurement. It should not automatically become the final maturity level because many mature knowledge bases do not require generative AI.
Common maturity-model mistakes
Treating migration as maturity
Moving files into one platform improves access but does not establish ownership, quality, lifecycle, search performance, or user success. Migrate only content that has a clear purpose and source status.
Measuring article count as success
A larger repository may create more duplication and search noise. Measure whether important questions are answered accurately and findably.
Assigning one score to the entire organization
Customer support, HR, engineering, IT, and policy knowledge may operate differently. Assess separately where ownership, risk, audience, or workflow differs.
Buying software before defining governance
A platform can enforce decisions, but it cannot decide who owns a policy, which source is authoritative, or what risk requires approval. Define the operating model before treating technology as the solution.
Using one review schedule for every article
Review frequency should reflect change rate, demand, business impact, and risk. A rarely changing glossary entry and a regulated operational procedure should not automatically follow the same schedule.
Declaring maturity after launching AI
Deployment proves that a system is connected, not that its sources are trustworthy or retrieval is reliable. Test source relevance, versions, permissions, citations, and high-risk answers.
Producing an assessment without a roadmap
A score has limited value unless it changes priorities. Translate each important gap into an owner, action, completion criterion, and measure.
Frequently asked questions
Is there an official Knowledge Base Maturity Model?
No single universal model governs all knowledge bases. Organizations adapt broader knowledge management, content governance, service knowledge, search, and AI-readiness principles to their own audiences and risks. Any synthesized model should disclose its basis and limitations.
How is knowledge base maturity different from knowledge management maturity?
Knowledge management maturity evaluates the organization’s broader capability across strategy, people, culture, processes, knowledge flow, and technology. Knowledge base maturity focuses more specifically on the operational system surrounding content: ownership, quality, lifecycle, structure, search, user outcomes, access, analytics, and retrieval.
How often should maturity be assessed?
Reassess after significant changes to the platform, organization, product, policy environment, audience, workflow, or AI use case. For an active improvement program, periodic reviews are useful, but the frequency should reflect business risk and rate of change rather than an arbitrary calendar rule.
Does buying better knowledge base software increase maturity?
Software can remove technical constraints and support stronger workflows, permissions, search, and analytics. It does not create accountable owners, content standards, governance decisions, or user-centered practices by itself.
Which maturity level is required for AI or RAG?
There is no universal minimum level. Before a high-impact AI deployment, the relevant content should have identifiable sources, owners, lifecycle controls, appropriate permissions, meaningful structure, and repeatable retrieval tests. The required controls should increase with the risk of an incorrect or unauthorized answer.
Should every knowledge base aim for Level 4?
No. The target should reflect the knowledge base’s audience, complexity, demand, and risk. A small, stable internal reference may perform well at Level 2, while safety-critical or high-volume customer knowledge may justify more advanced governance and measurement.
Who should own knowledge base maturity?
One accountable leader should coordinate the operating model, but maturity is shared across content owners, subject matter experts, support or operational teams, platform administrators, search specialists, analytics, and security. Ownership of the program should not replace ownership of the knowledge itself.
Turn the assessment into an operating decision
A Knowledge Base Maturity Model is useful when it reveals why users cannot trust, find, or apply an answer—and when that diagnosis changes what the organization does next.
Start with one clearly defined knowledge domain. Collect evidence across the relevant dimensions, identify the weakest critical capabilities, and set a target appropriate to the audience and risk. Then improve ownership, content, workflow, search, measurement, or retrieval in the order required by those dependencies.
The objective is not to obtain the highest possible score. It is to build a knowledge operation that consistently provides the right people and systems with trustworthy, usable, and appropriately controlled answers.