Independent knowledge base software guide Evidence-led Updated 2026

Sales enablement knowledge base: Practical guide
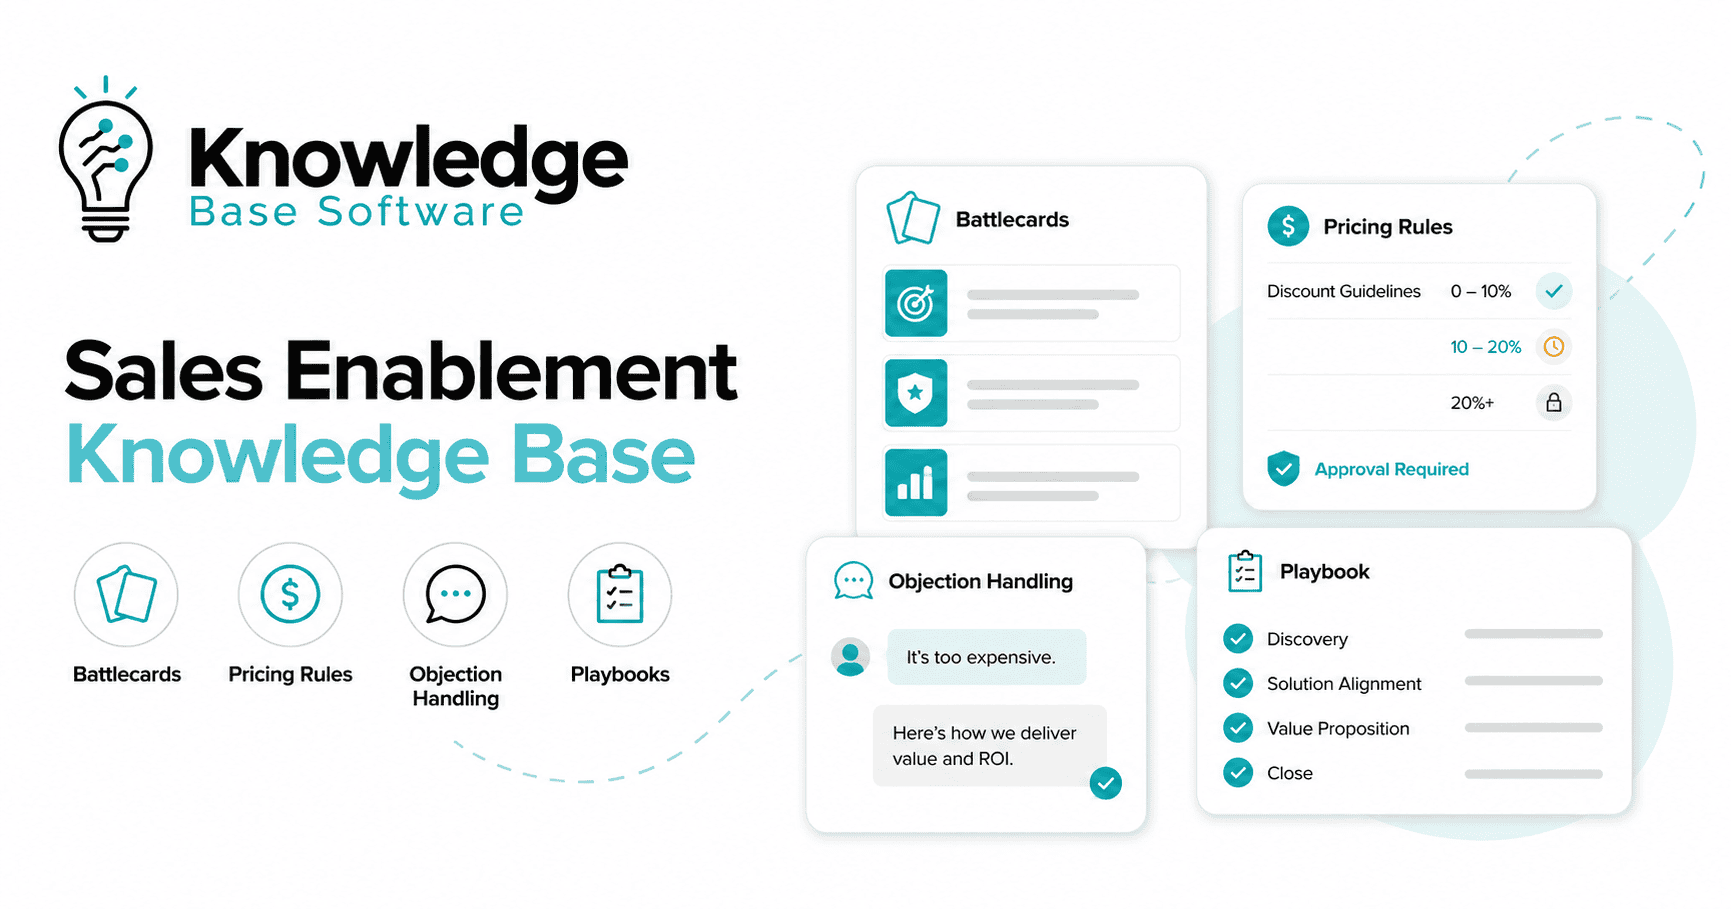
A sales enablement knowledge base is a governed, searchable layer of approved guidance that helps a seller decide what to say, send, ask, or do next. It should answer live deal questions—such as discount authority, competitor positioning, security review steps, and stage exit criteria—without forcing the rep to search through old decks or message a colleague.
The most useful design is not a large document library. It is a small set of structured answer cards connected to longer playbooks and surfaced in the CRM, messaging tools, or sales workspace. Each item needs an owner, audience, approval state, review trigger, and source of truth. This guide shows how to build that system and includes an original, reproducible retrieval test.
Reviewed: July 30, 2026. Product examples and plan requirements were checked against current official documentation on that date.
Quick answer
Start with the questions that interrupt deals most often. Publish one concise, approved answer for each question, then link it to evidence and a deeper playbook. At minimum, cover:
- competitor and scenario battlecards;
- pricing, packaging, and discount guardrails;
- objection-diagnosis cards;
- discovery and qualification prompts;
- security, legal, and procurement routes;
- stage definitions and CRM field guidance;
- customer proof approved for the relevant segment; and
- renewal, expansion, and handoff playbooks.
A CRM remains the system of record for accounts, opportunities, activities, and forecasts. An LMS remains the place for assigned learning and certification. The sales knowledge base supplies governed guidance at the moment of work. If the systems overlap, define one authoritative home for each fact and link to it rather than maintaining copies.
Design an operating model, not a document dump
A rep usually arrives with a situation, not a folder name: “The buyer wants net 60,” “They mentioned Atlas,” or “Can this account receive a pilot?” Organize navigation around those situations while retaining filters for product, segment, region, persona, and deal stage.
| Layer | Purpose | Typical length | Example |
|---|---|---|---|
| Answer card | Resolve one live question | 50–250 words | When does net 60 require approval? |
| Battlecard | Guide one competitive or objection scenario | One screen | Buyer is comparing Atlas |
| Playbook | Run a multi-step sales motion | 5–15 focused steps | Enterprise security review |
| Evidence asset | Substantiate an approved claim | As needed | Case study or security report |
| Policy source | Define the binding rule | Authoritative document | Discount approval policy |
Do not make the answer card another policy copy. State the operational answer, identify the source policy, and show its review date. When Finance changes the policy, one source change should trigger review of every dependent card. The site’s knowledge base governance framework explains how to assign accountable owners and approval workflows.
Use a consistent content schema
Structure makes content easier to scan, filter, retrieve, audit, and safely reuse in AI-assisted answers. A practical card schema is:
| Field | What to record | Why it matters |
|---|---|---|
| Question or trigger | The seller’s wording or the CRM condition | Matches the moment of need |
| Approved answer | A direct, bounded response | Reduces interpretation |
| Ask before answering | Diagnostic questions | Prevents a generic script |
| Do not claim | Known limitations and prohibited statements | Controls legal and trust risk |
| Next action | Asset, workflow, person, or CRM update | Turns information into execution |
| Evidence | Current customer proof or authoritative source | Supports the response |
| Audience metadata | Segment, region, persona, product, and stage | Improves filtering and permissions |
| Governance metadata | Owner, approver, status, last review, expiry trigger | Makes freshness visible |
Example battlecard
Trigger: The buyer says a lower-cost competitor is easier to deploy. Ask: “Which teams, approval controls, and audit requirements must the workflow support?” Position: explain fit against the requirements the buyer confirms. Do not claim: that the competitor lacks a feature unless a current, cited source proves it. Next action: attach the relevant implementation comparison and record the decision criteria in the CRM. Owner: Product Marketing. Review trigger: competitor packaging or product change.
Example pricing card
Question: “Can I offer this discount?” Answer: state the allowed range for the exact package, term, billing schedule, and region. Escalate when: any threshold or non-standard term is triggered. Do not expose: internal margin floors to audiences that do not need them. Source: the approved commercial policy, not a copied spreadsheet. Never publish fictional thresholds as company policy; examples must be visibly labeled as examples.
Deliver guidance in the sales workflow
Search quality matters, but opening a separate portal for every question still adds friction. Use CRM context to recommend—not silently decide—the relevant content. A competitor field can surface a reviewed battlecard; a procurement stage can surface legal and security routes; an industry value can filter proof points. Keep a visible link to the canonical page so the rep can verify the owner and review date.
This pattern is feasible in current products, although capabilities and licenses differ. HubSpot’s official playbooks documentation, last updated May 1, 2026, describes interactive cards in CRM records, sharing controls, version history, usage analytics, and stage-based recommendations. It also states that subscriptions, seats, permissions, and feature limits apply. Treat that as a product example, not a universal requirement. Before buying, verify the exact plan and test the workflow in your own account.
If content and CRM records exchange data, define direction, authentication, field mapping, retry behavior, and audit logs. The CRM integration guide covers those implementation controls in detail.
Protect sensitive sales knowledge
Not every seller needs every commercial fact. Separate broadly usable messaging from restricted pricing floors, legal advice, customer-confidential evidence, and unreleased roadmap information. Grant the minimum access needed for a role, review it on a schedule, and remove it after role changes. This follows the least-privilege principle described in NIST SP 800-171 Rev. 3.
| Content | Default audience | Approval | Review trigger |
|---|---|---|---|
| Public product facts | All sellers | Product Marketing | Product release |
| Competitor positioning | Sales and approved partners | Product Marketing and Legal where needed | Competitor change |
| Discount rules | Relevant sales roles | Finance or deal desk | Packaging or policy change |
| Security responses | Sales, Solutions, and Security | Security and Legal | Control or policy change |
| Internal margin data | Named commercial roles only | Finance | Immediate change or quarterly review |
Build the knowledge base in seven steps
1. Collect decision questions
Sample sales calls, CRM notes, enablement requests, onboarding questions, deal-desk tickets, and search logs. Record the exact language reps use and the decision each answer should support. Start with 25–50 high-frequency or high-risk questions, not every historical asset.
2. Name the authoritative source
For each question, identify who can approve the answer and which system contains the binding fact. If no source or accountable owner exists, resolve that governance gap before publishing.
3. Write the smallest useful card
Lead with the answer. Add qualifiers, questions to ask, prohibited claims, evidence, and the next action. Link to a longer playbook only when the task has multiple steps.
4. Add metadata and synonyms
Include buyer wording, product aliases, competitor names, commercial terms, region, segment, persona, stage, and content status. Synonyms should help retrieval without concealing important distinctions.
5. Configure approvals and access
Use draft, review, approved, superseded, and archived states. Restrict sensitive cards, keep an audit trail, and test with ordinary user accounts rather than relying on an administrator preview.
6. Test retrieval with real wording
Create an answer key of real questions and the expected canonical card. Test exact terms, paraphrases, abbreviations, and risky near-matches. The site’s AI answer quality testing guide adds groundedness and citation checks if an assistant generates answers.
7. Launch with a feedback route
Let reps flag “outdated,” “unclear,” “missing,” or “wrong audience.” Route the signal to an owner with a service level based on risk. A legal or pricing error should have a faster route than a minor wording suggestion.
A focused 30-day launch plan
A short launch should prove one workflow rather than move every asset. Choose a sales segment and a bounded set of questions, then compare retrieval and task feedback before expanding.
| Period | Work | Exit evidence |
|---|---|---|
| Days 1–5 | Collect questions, name owners, identify policy sources, and freeze a retrieval test set. | Prioritized question inventory and answer key |
| Days 6–12 | Write 25–50 cards, add metadata, configure states, and review sensitive claims. | Approved pilot collection with visible owners |
| Days 13–18 | Configure permissions and one contextual CRM entry point. Test as ordinary users. | Access matrix and workflow evidence |
| Days 19–24 | Run retrieval, permission, link, mobile, and accessibility checks. Repair failures. | Recorded test results and accepted residual risks |
| Days 25–30 | Release to the pilot group, observe queries, collect explicit task feedback, and assign gaps. | Launch review with a keep, change, or stop decision |
Do not set an adoption target without defining the eligible population and expected use moments. A rep who had no competitive deal should not be penalized for not opening a competitor battlecard. Likewise, a high view count may indicate that an answer is hard to understand. Combine usage with query-level success and qualitative review.
Original test: structured cards improved retrieval
We ran a deterministic local retrieval test on July 30, 2026. It used a synthetic—but fully disclosed—set of 12 sales cards covering discounts, payment terms, two competitors, security, CFO discovery, renewals, CRM stages, pilots, healthcare proof, budget objections, and legal redlines. We wrote 12 queries before scoring, with one expected card per query.
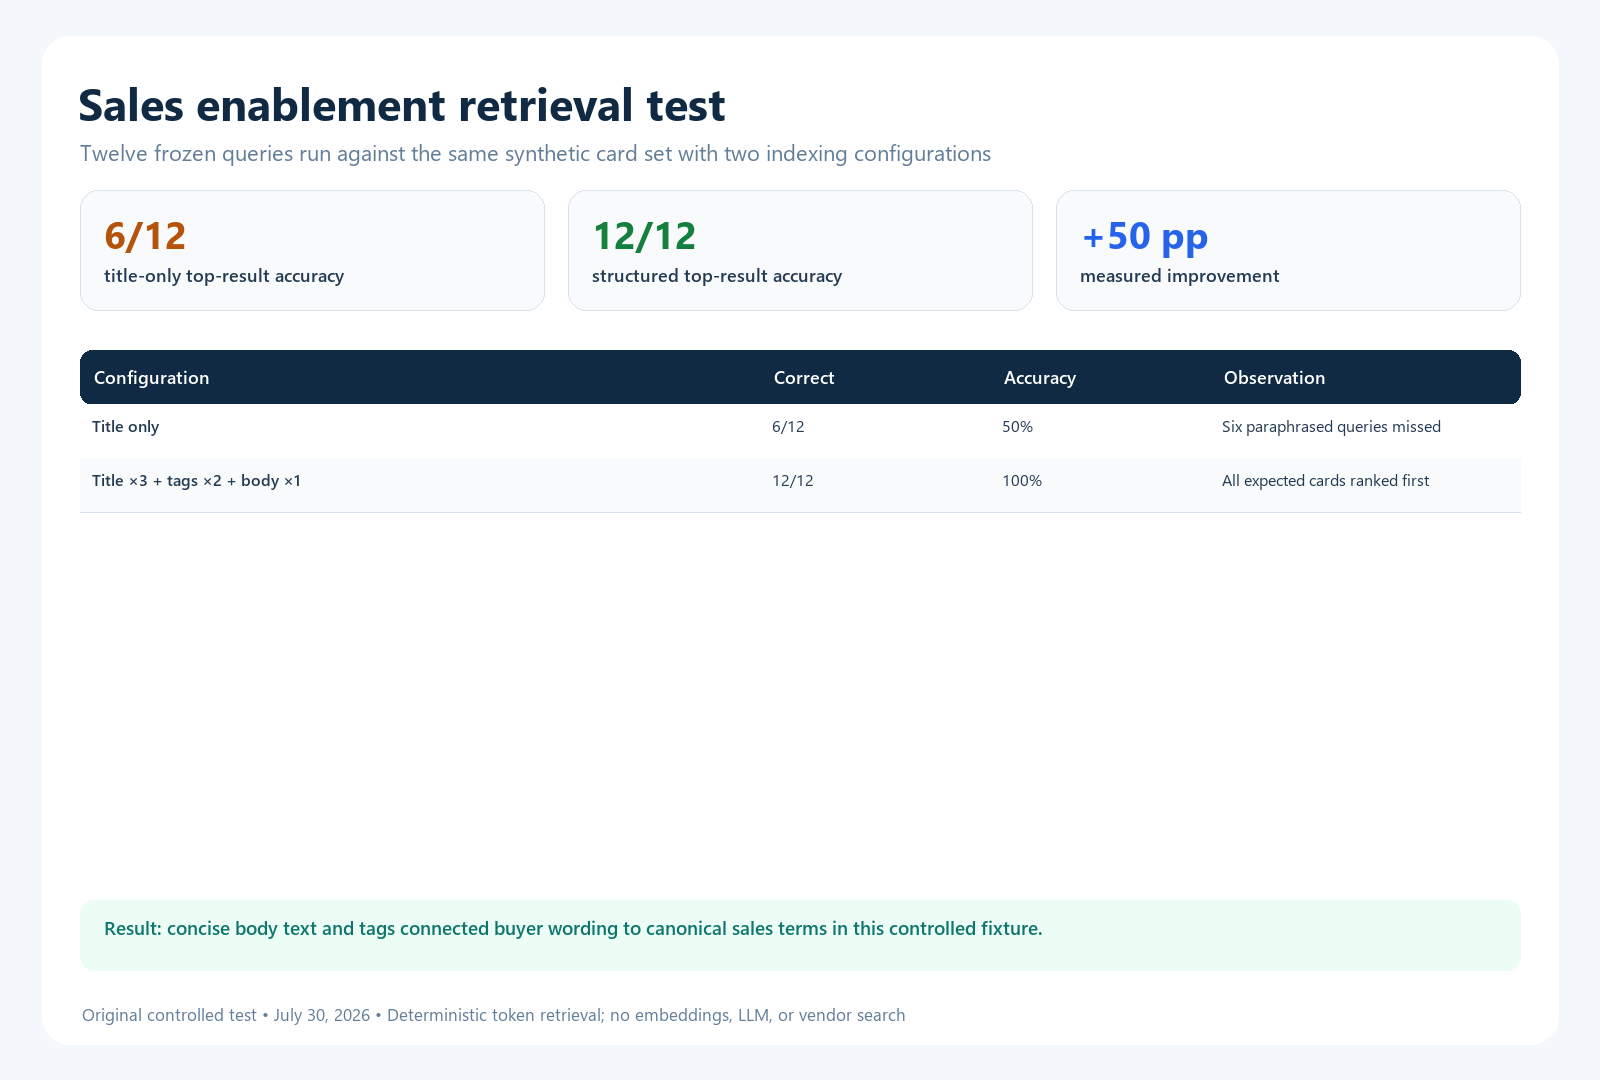
| Configuration | Fields searched | Top-result accuracy | Important observation |
|---|---|---|---|
| Baseline | Title only | 6/12 (50%) | All six paraphrased queries missed because their buyer wording did not appear in the titles |
| Structured | Title ×3, tags ×2, body ×1 | 12/12 (100%) | Metadata connected buyer wording to canonical terms |
The tokenizer lowercased alphanumeric terms, removed a fixed list of common English words, and applied minimal plural normalization. It did not use embeddings, an LLM, query expansion, click data, or vendor search. Examples that title-only missed included “who approves net 60,” “questions to ask a finance leader,” and “legal wants an indemnity change.” Tags and concise body text supplied the missing vocabulary.
How to reproduce the test
- Create 12 rows with
id,title,body, andtags. - Create 12 query rows with a frozen expected ID.
- Tokenize all fields with the same rules.
- Score a title match as 3, a tag match as 2, and a body match as 1 for every query token.
- Sort by score, keep the original row order for ties, and compare the first result with the answer key.
- Review every failure before changing metadata; rerun a separate holdout set after tuning.
Limitations: this is a small English synthetic fixture, not a benchmark of any platform or an estimate of production search accuracy. The structured set was intentionally authored with useful metadata. A real evaluation needs unseen queries, permission filtering, typo handling, latency measurement, and reviewer judgment. The test supports one narrow conclusion: titles alone were insufficient for this dataset.
Measure usefulness without claiming causation
| Metric | Definition | Use | Do not infer |
|---|---|---|---|
| Search success | Queries where the expected useful card is found under a stated test | Findability QA | That a deal was won |
| Content adoption | Eligible sellers who viewed or used a card | Workflow reach | That the content changed behavior |
| Freshness compliance | Approved items reviewed before their due date | Governance health | That every fact is correct |
| Task feedback | Seller reports that the card answered the immediate question | Perceived usefulness | Causal revenue impact |
| Deal outcome association | Outcome differences for deals where content was logged | Generate hypotheses | That content caused the difference |
Separate observation from attribution. Reps may use more content on complex deals, so a simple correlation with win rate can be misleading. Define eligibility, time windows, and events before collecting data. Use the knowledge base benchmarking guide to document a defensible measurement design.
Selection and launch checklist
- Can sellers find a card using buyer language, aliases, and abbreviations?
- Can the system filter results by region, product, segment, role, and approval state?
- Are owners, approvers, review dates, versions, and source links visible?
- Can sensitive pricing and legal content be restricted and audited?
- Can a CRM surface canonical guidance without creating uncontrolled copies?
- Can editors preview what an ordinary rep can access?
- Can search failures and seller feedback create an assigned review task?
- Can content and metadata be exported in a usable format?
- Can AI answers cite the approved source and refuse when evidence is missing?
- Have license, seat, usage, integration, and implementation costs been tested?
Frequently asked questions
Is a sales enablement knowledge base the same as a CRM?
No. A CRM records accounts, deals, activities, and forecasts. The knowledge base provides governed guidance for decisions and conversations. Integrate them, but keep a clear system of record for every fact.
Should battlecards be one page?
They should usually fit the live situation without scrolling through a report. Link to deeper evidence rather than compressing every research note into the card.
How often should pricing guidance be reviewed?
Use an immediate event trigger for pricing, package, approval, or regional policy changes, plus a scheduled review. The risk of the fact should determine the interval.
Can AI write answers for sellers?
It can assist retrieval and drafting, but high-risk answers need permission-aware sources, citations, freshness controls, refusal behavior, and human approval. Never let a model invent pricing, legal, security, or competitor claims.
Sources and methodology
Current capability examples were verified against HubSpot’s official playbooks documentation and Salesforce’s official Sales Enablement content-format guidance. Access-control guidance uses NIST SP 800-171 Rev. 3. The original test used a local deterministic fixture and does not represent vendor performance. Recheck plan gates and product behavior in your own account before implementation.